
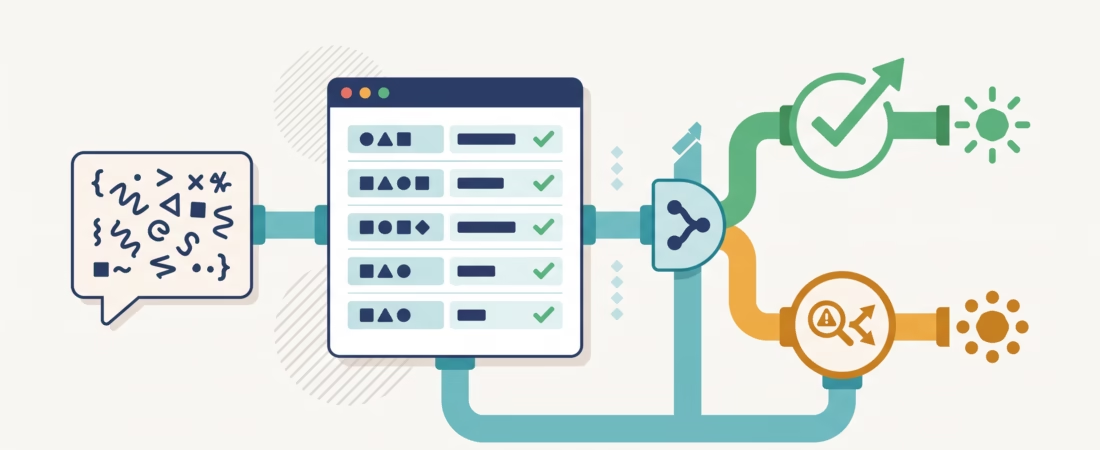
If your application needs a model response it can read reliably, a prompt that says “return JSON” is a weak contract. LLM structured outputs let you define the shape you expect, then ask a provider or framework to produce data that follows that schema. That makes parsing easier. It does not make the answer true, complete, or safe to use without checks.
This guide walks through the difference between JSON prompting and schema-constrained output, shows a small Pydantic example, and gives you a practical validation loop. The goal is not to remove every failure. It is to make failures visible before they reach your database, UI, or business logic.
What are LLM structured outputs?
Structured output means asking a model for data in a defined shape rather than an open-ended paragraph. A schema might require an object with a string called summary, an array called action_items, and a fixed set of values for priority.
The schema acts like a boundary for the response format. Depending on the provider and the selected model, the API may constrain generation to a supported JSON Schema, or an SDK may parse the result into a typed object. Frameworks such as LangChain can select a provider-native strategy or use a tool-based strategy when the model lacks native support. Those behaviors vary by provider, model, and framework version, so check the documentation for the exact combination you ship.
The basic idea is simple: define the fields your program needs, request an answer in that shape, then validate the values before acting on them.
Why “please return JSON” often fails
A prompt can ask for JSON, but the model may still add an introduction, omit a key, return a number as text, or use a value your code did not expect. Even when the response parses as JSON, it might not match the shape your program assumes.
For example, this is valid JSON:
{
  "customer_id": "not-a-number",
  "priority": "urgent-ish"
}
But suppose your application expects an integer customer_id and one of three priority values: low, normal, or high. A JSON parser will accept that object. Your application should not.
There are three common approaches, and they solve different problems:
- Prompt-only JSON: Ask for JSON in natural language. This is flexible, but your code must expect formatting and shape errors.
- JSON mode: Where an API offers it, request syntactically valid JSON. That usually does not guarantee your required fields, types, or enum values.
- Schema-constrained output: Supply a supported schema and have the API constrain the response to that shape. This can reduce structural errors, but it cannot check every business rule or establish that a claim is true.
OpenAI’s documentation makes this distinction directly: Structured Outputs target schema adherence, while JSON mode targets valid JSON syntax. Anthropic also documents JSON Schema-based output separately from strict tool use. Treat these as related features, not interchangeable names for the same thing.
Define a small schema before writing a long prompt
Start with the smallest useful response. If you are extracting a support ticket, you may need a category, a short summary, and a confidence note. Resist the urge to model every possible detail on day one; every field becomes another thing your code and tests must handle.
Here is a simple Pydantic model. It defines required fields, a constrained category, and a list of labels:
from typing import Literal
from pydantic import BaseModel, Field

class TicketSummary(BaseModel):
    category: Literal["billing", "bug", "account", "other"]
    summary: str = Field(description="One sentence based only on the ticket")
    labels: list[str]
    needs_human_review: bool
The exact API call depends on your provider’s SDK. Some SDKs accept a Pydantic class and generate the schema for you. Others expect a JSON Schema object or a provider-specific response-format setting. OpenAI and Anthropic both document SDK parsing helpers; Gemini documents schema output with typed-library examples. Before copying an example into production, confirm that your chosen model supports the schema features you use.
Descriptions can clarify a field’s meaning, but they are not substitutes for validation. “One sentence based only on the ticket” guides generation; a separate check still needs to reject an empty string or a summary that includes unsupported claims.
Required fields, optional fields, and enums
Mark a field required when the rest of your program cannot proceed without it. Use an enum or literal set when downstream behavior depends on a known set of choices. If a value can genuinely be absent, represent that absence explicitly using the pattern supported by your provider instead of hoping the model writes null consistently.
Optional fields deserve special care. “Optional” might mean the key can be omitted, or it might mean the key is always present but can contain a null value. Those are different shapes. Decide which one your code handles, then express it in the schema and test it.
Nested objects and arrays work well when each element has a clear type. Keep the first version readable. A deeply nested schema can be difficult to debug and may exceed a provider’s supported subset. The schema’s purpose is to make the interface boring and predictable, not to encode your entire domain model at once.
Schema-valid does not mean factually correct
This is the part teams tend to learn the hard way. A schema can require a date string, but it cannot tell whether the date was present in the source text. It can restrict a category to billing or bug, but it cannot guarantee the chosen category is right. Shape is not truth.
Think of checks in layers:
- Transport: Did the request succeed, and did you receive a complete response rather than a timeout or truncated result?
- Provider outcome: Was the response a refusal or another non-answer that your application must handle?
- Structure: Does the result match the schema and parse into your type?
- Business rules: Are the values allowed in this workflow? Does the referenced account exist? Is the amount within the permitted range?
- Grounding: When the output summarizes supplied material, can important claims be traced back to that material?
Not every application needs all five checks. A low-risk tag suggestion can tolerate more uncertainty than an automated refund decision. Pick checks based on what a bad value can do, not on how neat the JSON looks.
Use a generate, validate, and decide loop
A reliable pipeline has an explicit decision after validation. “Retry until it works” is not a policy; it can waste requests and hide a broken schema. A practical flow looks like this:
response = call_model(input_text, schema=TicketSummary)

if response.is_refusal or not response.is_complete:
    send_to_review("No usable model result")
else:
    result = parse_as_ticket_summary(response)
    errors = validate_business_rules(result)

    if not errors:
        accept(result)
    elif can_repair_safely(errors):
        repaired = make_one_repair_attempt(result, errors)
        if validate_business_rules(repaired):
            accept(repaired)
        else:
            send_to_review("Validation still failed")
    else:
        send_to_review("Validation failed")
In a real SDK, the names and response fields will differ. The important part is the control flow: handle refusal and incomplete responses, parse, run your own checks, then accept, make a limited repair attempt, or reject. Do not blindly feed invalid output back to the model if the result could trigger a payment, change permissions, or send a message.
Use retries mainly for transient API failures, with a cap and a backoff policy. A schema mismatch is often a configuration or compatibility problem; repeating the same request may not fix it. If you do ask the model to repair a value, include the validation error and original source, but do not let the repair step invent missing evidence.
Provider-native output or a framework?
Provider-native structured output is usually the clearest place to start when your chosen API supports it. You see the provider’s schema rules, refusal handling, and response format directly. The trade-off is that each provider has its own request shape and supported schema subset.
A framework can make application code more portable and provide a common result type. LangChain, for example, documents provider strategies for native structured output and tool strategies for models that do not offer native support. That convenience adds another layer: check the framework version, model capability profile, and actual strategy selected at runtime. A single high-level call can hide meaningful differences between providers.
If you are learning the API stack, build one small example with the raw provider SDK first. Then add a framework if it makes a real part of the application easier. Our guide to LangChain fundamentals covers what the framework adds over direct model calls.
Structured outputs are not function calling
Structured output describes the shape of a response your application wants to receive. Function or tool calling lets a model request that your application run a named function, usually with arguments. Those arguments may also use a schema, but the application still decides whether to execute the requested action.
For example, a model can return a structured shipping summary for your UI. If it asks to call cancel_order, your code must check the order, the user’s permissions, and the cancellation policy before doing anything. A valid tool-argument object is not authorization.
A short checklist before shipping
- Choose the smallest response shape your application needs.
- Confirm your provider and model support the schema features you used.
- Handle refusals, incomplete responses, and API errors separately from schema errors.
- Validate application rules after parsing; add grounding checks where unsupported claims matter.
- Set a retry limit, and route unresolved or high-impact cases to a person.
- Log the model, schema version, validation outcome, and a request identifier without logging secrets or unnecessary personal data.
If you are building your first LLM API feature, try this with a harmless extraction task first. Save a few realistic examples, including missing and ambiguous fields, then inspect how your schema and validation rules behave. Once the failure path is clear, connect the result to application logic.
FAQ about LLM structured outputs
Are structured outputs the same as JSON mode?
No. JSON mode generally focuses on valid JSON syntax. Structured outputs use a supplied schema to constrain the response shape, where the provider supports that feature. Neither one proves that the values are correct.
Does a schema stop hallucinations?
No. It can constrain fields and types, but a model can still put a false or unsupported value in a correctly typed field. Validate business rules and check important claims against source data.
Should I use Pydantic or write JSON Schema by hand?
Use whichever fits your stack and provider. Pydantic is convenient in Python because it combines type declarations and validation. Direct JSON Schema can be a better fit when your app shares schemas across languages. Check whether your provider supports the generated schema before relying on it.
When should I use structured output instead of tool calling?
Use structured output when the model should return data for your application to display or process. Use tool calling when the model needs to request an application action. Your code remains responsible for permission checks and execution.
What should happen when validation fails?
First identify whether the issue is a transient API failure, incomplete response, schema mismatch, or business-rule violation. Retry only when it makes sense and cap attempts. For high-impact cases or unresolved errors, reject the result or route it for human review.
Next step: build one typed response
Pick a small task, define a schema with only the fields your program needs, and test it with clear, missing, and ambiguous inputs. Then add application-level checks. That exercise will teach you more about reliable model integration than adding another sentence to a “return JSON” prompt.
Sources: OpenAI Structured Outputs; Anthropic structured outputs; LangChain structured output; Google Gemini structured outputs.