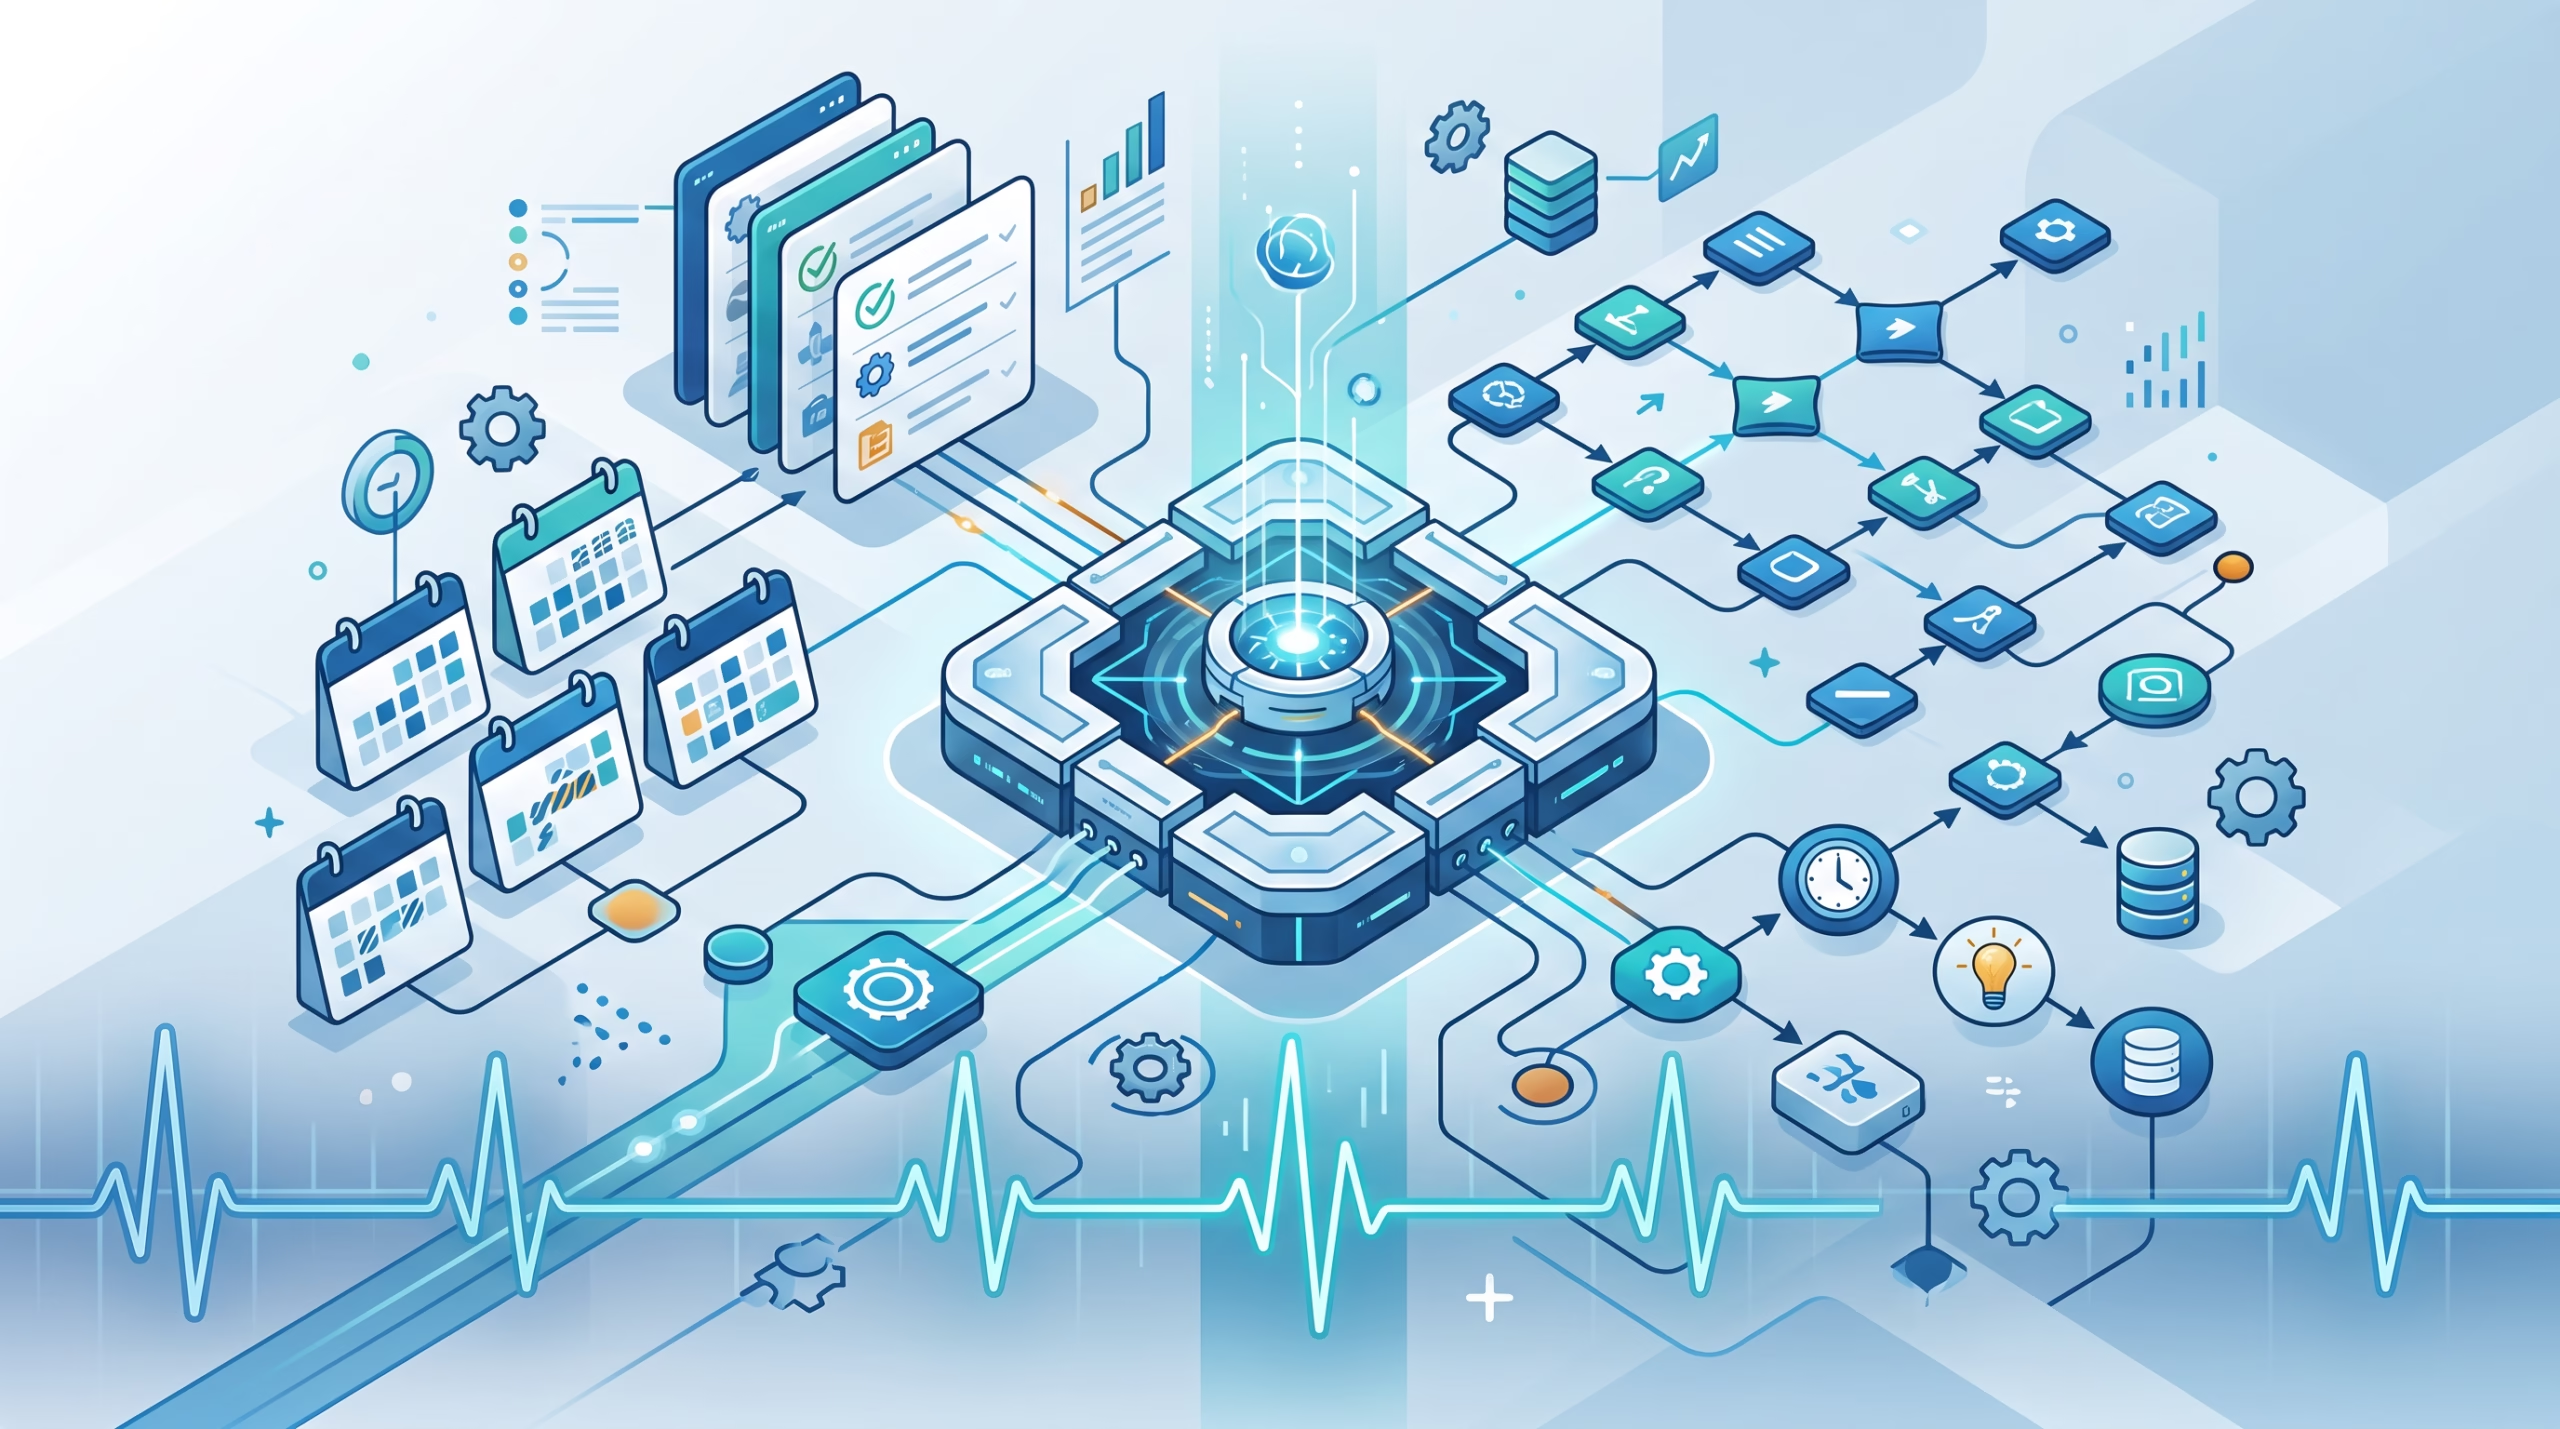
OpenClaw automation is the set of tools that lets an agent do work outside a normal chat turn: scheduled jobs, detached tasks, event hooks, standing instructions, heartbeat checks, and durable multi-step flows. That sounds like one feature until you try to operate it. Then the labels matter.
The best way to read the OpenClaw automation docs is as a routing guide. If you need a 9 AM report, use an automation. If you need to inspect detached work, use tasks. If the job has several steps and can stop halfway through, use Task Flow. If a lifecycle event should run a short script, use hooks. If the agent needs permanent authority, write standing orders. If the main session needs a quiet periodic nudge, heartbeat has that job.
My take: the real value here is not that OpenClaw can schedule things. Plenty of tools can schedule things. The value is that timing, authority, execution records, and flow state are not mashed into one giant prompt. That split is what keeps automation from turning into a haunted chat transcript with a cron expression stapled to it.
The useful definition of OpenClaw automation
The Automation overview page describes OpenClaw as running background work through tasks, scheduled jobs, event hooks, and standing instructions. It also gives a decision guide for choosing the right mechanism.
That decision guide is worth taking literally. “Automation” in everyday speech usually means “make the computer do it later.” In OpenClaw, that is too vague. A scheduled reminder and a durable approval workflow do not fail the same way. A hook that logs /reset is not the same as a recurring inbox triage job. A standing order is not a scheduler.
OpenClaw’s automation surfaces map to different questions:
- When should work start? Use automations.
- What detached work is running or finished? Use background tasks.
- How do several steps survive pauses, retries, and restarts? Use Task Flow.
- What should happen when the Gateway emits an event? Use hooks.
- What is the agent allowed to do without asking every time? Use standing orders.
- Should the main session periodically notice something? Use heartbeat.
That is the whole mental model. The rest of the docs make more sense once you stop trying to make one mechanism cover all six questions.
OpenClaw automation in one decision table
Here is the practical version for operators:
| Need | Use | Why |
|---|---|---|
| Run a report every weekday morning | Automations | The scheduler owns the clock, run history, delivery, and failure handling. |
| Check what detached runs are active | Background tasks | Tasks are the ledger for ACP runs, subagents, automations, CLI runs, and media jobs. |
| Track a multi-step workflow with waits | Task Flow | Flows keep status, JSON state, revision, and linked task records. |
| React when a session resets or a message event occurs | Internal hooks | Hooks run trusted Gateway-side handlers for lifecycle and message events. |
| Gate tool calls or modify plugin behavior | Plugin hooks | Typed plugin hooks use api.on(...) and have their own permission gates. |
| Give the agent a recurring responsibility | Standing orders plus automations | Standing orders define authority; automations enforce timing. |
| Let the main session notice ambient updates | Heartbeat | Heartbeat is a system-owned monitor automation, not a general task list. |
The table also shows the trap. “Can OpenClaw automate this?” is usually the wrong first question. Ask what should own the failure mode. If the clock is the hard part, use automations. If audit is the hard part, inspect tasks. If half-finished state is the hard part, design a flow.
Automations are for timing and external triggers
Automations are OpenClaw’s built-in scheduler. The docs say the scheduler persists jobs, wakes the agent at the right time, and can deliver output to a chat channel, webhook, or nowhere. The old openclaw cron command remains an alias, but the current name is openclaw automations.
That small rename matters. Cron is only one schedule shape. OpenClaw automation schedules include:
atfor one-shot timestamps or relative times.everyfor fixed intervals.cronfor 5-field or 6-field cron expressions, with optional timezone handling.on-exitfor firing when a watched command exits.streamfor firing from batched output lines produced by a supervised long-lived command.
Payloads are separate from schedules. A job can enqueue a system event, run a model-backed agent message, run a command on the Gateway host, or execute a headless script. Agent-turn jobs can also pin model choice, fallback behavior, thinking level, light context, and tool policy.
The architecture detail to remember: automation jobs run inside the Gateway process, not inside the model. Job definitions, runtime state, and run history persist in OpenClaw’s shared SQLite state database. The model may execute the requested work, but it does not own the schedule.
That is why automations are the right surface for reports, reminders, scheduled checks, webhook-triggered work, and command-based probes. The Gateway owns the clock and the run record. The agent owns the interpretation when the payload asks for an agent turn.
Background tasks are the audit ledger
Background tasks are not schedulers. The tasks page says this directly: tasks are records, not schedulers. They track detached work that runs outside the main conversation session.
Task records cover ACP runs, subagent spawns, automation job runs, CLI operations, and session-backed media generation. They move through statuses such as queued, running, succeeded, failed, timed_out, cancelled, and lost.
That ledger is not just nice to have. Detached work needs a place to land. A subagent can finish after the parent turn has moved on. An automation can succeed but fail delivery. A command can time out. If all of that is only narrated in chat, debugging becomes archaeology.
The docs also give retention expectations: terminal records are kept for 7 days, while lost records are kept for 24 hours. That is long enough to audit recent work without pretending the task ledger is a permanent archive.
Use openclaw tasks list, openclaw tasks show, openclaw tasks cancel, and openclaw tasks audit when the question is “what happened to the work?” Use automations when the question is “when should this work start?” Mixing those up leads to awkward designs.
Task Flow is for multi-step work
Task Flow sits above background tasks. The docs define a flow as a durable record of multi-step work with its own status, JSON state, revision counter, and linked task records. That is the key line.
A single report run may only need an automation and one task record. A more serious workflow needs more structure. Imagine a weekly research job that collects sources, rejects stale data, drafts a summary, waits for approval, and posts the approved version. If the Gateway restarts after collection but before approval, the right answer is not “ask the model to infer what happened.” The right answer is a flow record.
Task Flow gives the larger run a handle. It can be inspected with:
openclaw tasks flow list
openclaw tasks flow show <lookup>
openclaw tasks flow cancel <lookup>
It also has the boring reliability mechanics that long-running work needs. Flow records persist in the shared SQLite state database. Each write bumps a revision counter, so stale writers have to re-read instead of overwriting newer state. Cancellation intent is sticky. Finished flows are pruned after 7 days, while resumable blocked flows are retained regardless of age.
Compared with general durable-execution platforms such as Temporal, OpenClaw’s Task Flow is narrower and more agent-specific. Temporal talks about workflow executions surviving failures by recording event history. OpenClaw’s flow layer is focused on agent work inside the Gateway: owner session, linked task records, child runs, inspection, cancellation, and delivery paths. Different tool, different center of gravity.
Hooks are for Gateway events, not long-running jobs
OpenClaw has more than one hook system, and the distinction matters.
Internal hooks are JavaScript or TypeScript handlers that run in the Gateway process when OpenClaw emits events. They can react to lifecycle events such as /new, /reset, /stop, session compaction, Gateway startup, and message flow. The hooks docs are blunt about the security model: internal hooks are trusted code, not sandboxed scripts.
That makes hooks powerful and a little sharp. Use them for short, bounded side effects: logging a reset, saving context, reacting to a known lifecycle event, or installing a bundled hook such as a command logger. Do not use an internal hook as a casual home for long-running work. The docs warn that there is no general durable event queue, automatic retry, or exactly-once guarantee for internal handlers.
Plugin hooks are a separate system. A plugin registers typed handlers with api.on("hook_name", handler). Those hooks can observe or change prompt building, tool calls, replies, message delivery, model timing, and Gateway lifecycle. They have plugin loading rules and permission gates, including explicit conversation-access settings for non-bundled plugins.
Then there are webhooks, which are not internal hooks at all. Webhooks let an external service trigger work through authenticated HTTP ingress. If another service is starting the agent, think webhook. If Gateway lifecycle is triggering trusted local code, think internal hook. If a plugin is gating tools or replies, think plugin hook.
Standing orders define authority
Standing orders answer a different question: what is the agent allowed to own?
The standing orders docs frame them as permanent operating authority for defined programs. A standing order should describe scope, triggers, approval gates, and escalation rules. The recommended place is AGENTS.md, because workspace bootstrap loads that file every session.
This is where many automation setups get sloppy. A schedule without authority produces a job that wakes up and asks what to do. Authority without a trigger produces a responsibility that may never run. The clean pattern is both:
Standing order: You own daily inbox triage within these limits.
Automation: Every weekday at 8 AM, execute inbox triage per standing orders.
The agent does not need a giant repeated prompt if the standing order already defines the program. The automation prompt can stay short because the durable authority lives in the workspace file. That also makes review easier. Boss can inspect the standing order once instead of reverse-engineering authority from five scheduled job messages.
Heartbeat is ambient monitoring
Heartbeat is easy to misuse because it feels like a free scheduler. It is not. Heartbeat is a system-owned automation that runs periodic main-session turns so the model can surface anything that needs attention without spamming the owner.
The default interval is 30 minutes. Heartbeat turns do not create background task records. They are main-session awareness checks, not detached work records. The docs also note that the heartbeat prompt tells the agent to keep recurring work in automation jobs and not infer old tasks from prior chats.
That design choice is healthy. Old versions of agent systems often tried to turn chat memory into commitments. It sounds convenient until the agent starts “remembering” stale requests and waking you about ghosts from a month ago. The current OpenClaw automation page explicitly says the inferred commitments experiment was removed in v2026.8.1. Reminders and scheduled work should now be explicit automations.
Use heartbeat for ambient main-session awareness. Use automations for scheduled programs. Use tasks and flows to inspect detached work. That boundary keeps the owner from getting mystery follow-ups and keeps the system honest about what was actually scheduled.
A practical setup pattern
For a real agent program, build from the outside in:
- Write the standing order first. Define scope, approval gates, escalation rules, and what the agent must not do.
- Create an automation for timing or an event trigger. Keep the job prompt short and reference the standing order.
- Choose the payload deliberately. Use an agent message for judgment, a command for deterministic probes, and a script for headless tool orchestration.
- Use isolated sessions when the run should start fresh. Use a named or persistent session when prior run context is deliberately part of the workflow.
- Inspect task records after runs. Delivery failure and execution failure are different problems.
- Add Task Flow only when the work has multiple steps, waits, retries, approval gates, or child tasks worth tracking.
- Use hooks for short Gateway-side event reactions. Move durable work into automations or plugin-owned controllers.
This pattern is less exciting than saying “make my agent autonomous.” Good. Autonomous work should be a little boring. The schedule should be visible, the authority should be written down, the run should have a record, and the owner should know exactly where to look when it fails.
FAQ about OpenClaw automation
Is OpenClaw automation just cron for agents?
No. Cron expressions are one schedule type. OpenClaw automations also support one-shot timestamps, intervals, command-exit triggers, stream triggers, webhooks, Gmail-related triggers, payload policies, delivery rules, and run history.
Do all automation runs create background tasks?
The automation docs say every automation run creates a background task record. Heartbeat is the exception operators notice most often: heartbeat is a system-owned monitor automation, but heartbeat turns do not create background task records.
When should I use Task Flow?
Use Task Flow when a job has multiple steps and you would need to explain where it stopped. A one-shot reminder does not need a flow. A research pipeline with collection, filtering, approval, delivery, and retries probably does.
Are hooks safe for heavy automation?
Internal hooks run trusted code inside the Gateway process and are not sandboxed. Keep them short and bounded. If the work needs retry, state, delivery, or inspection, use an automation, Task Flow, or a plugin service designed for that lifecycle.
What replaced inferred commitments?
Explicit automations. The Automation overview says inferred commitments were removed in v2026.8.1. OpenClaw no longer extracts follow-ups from conversations or delivers them through heartbeat. For reminders or scheduled work, create an automation with the schedule and instructions you choose.
Final take
OpenClaw automation works best when you stop treating automation as one magic bucket. Automations own the clock. Tasks record detached work. Task Flow records multi-step state. Hooks react to Gateway events. Standing orders define authority. Heartbeat keeps the main session lightly aware.
That separation is the whole point. It gives self-hosted agent operators something better than a clever prompt: a system they can inspect, cancel, audit, and repair when the real world interrupts the run.