
OpenClaw bundled hooks are the built-in way to attach small, trusted automation to Gateway lifecycle events without writing a custom hook from scratch. That sounds simple, but it is easy to overread what they promise. A bundled hook is not a workflow engine. It is not a retry queue. It is not proof that an event happened exactly once.
Think of bundled hooks as operator controls. Each one listens for a narrow event, performs a narrow side effect, and leaves behind something you can inspect: a log line, an added bootstrap file, a compaction notice, or a memory excerpt. Used that way, they are useful. Used as background job glue for heavy work, they get risky fast.
This guide explains the five hooks OpenClaw ships today, what each one does, how to verify it, and where the sharp edges are. The opinionated version: enable the smallest hook that gives you the operational behavior you need, then verify the side effect instead of trusting the config report.
What OpenClaw bundled hooks actually are
OpenClaw internal hooks are JavaScript or TypeScript handlers that run inside the Gateway process when OpenClaw emits an internal event. The bundled hooks are the maintained set that ship with OpenClaw itself. You do not need to create a hook package or write a handler to use them.
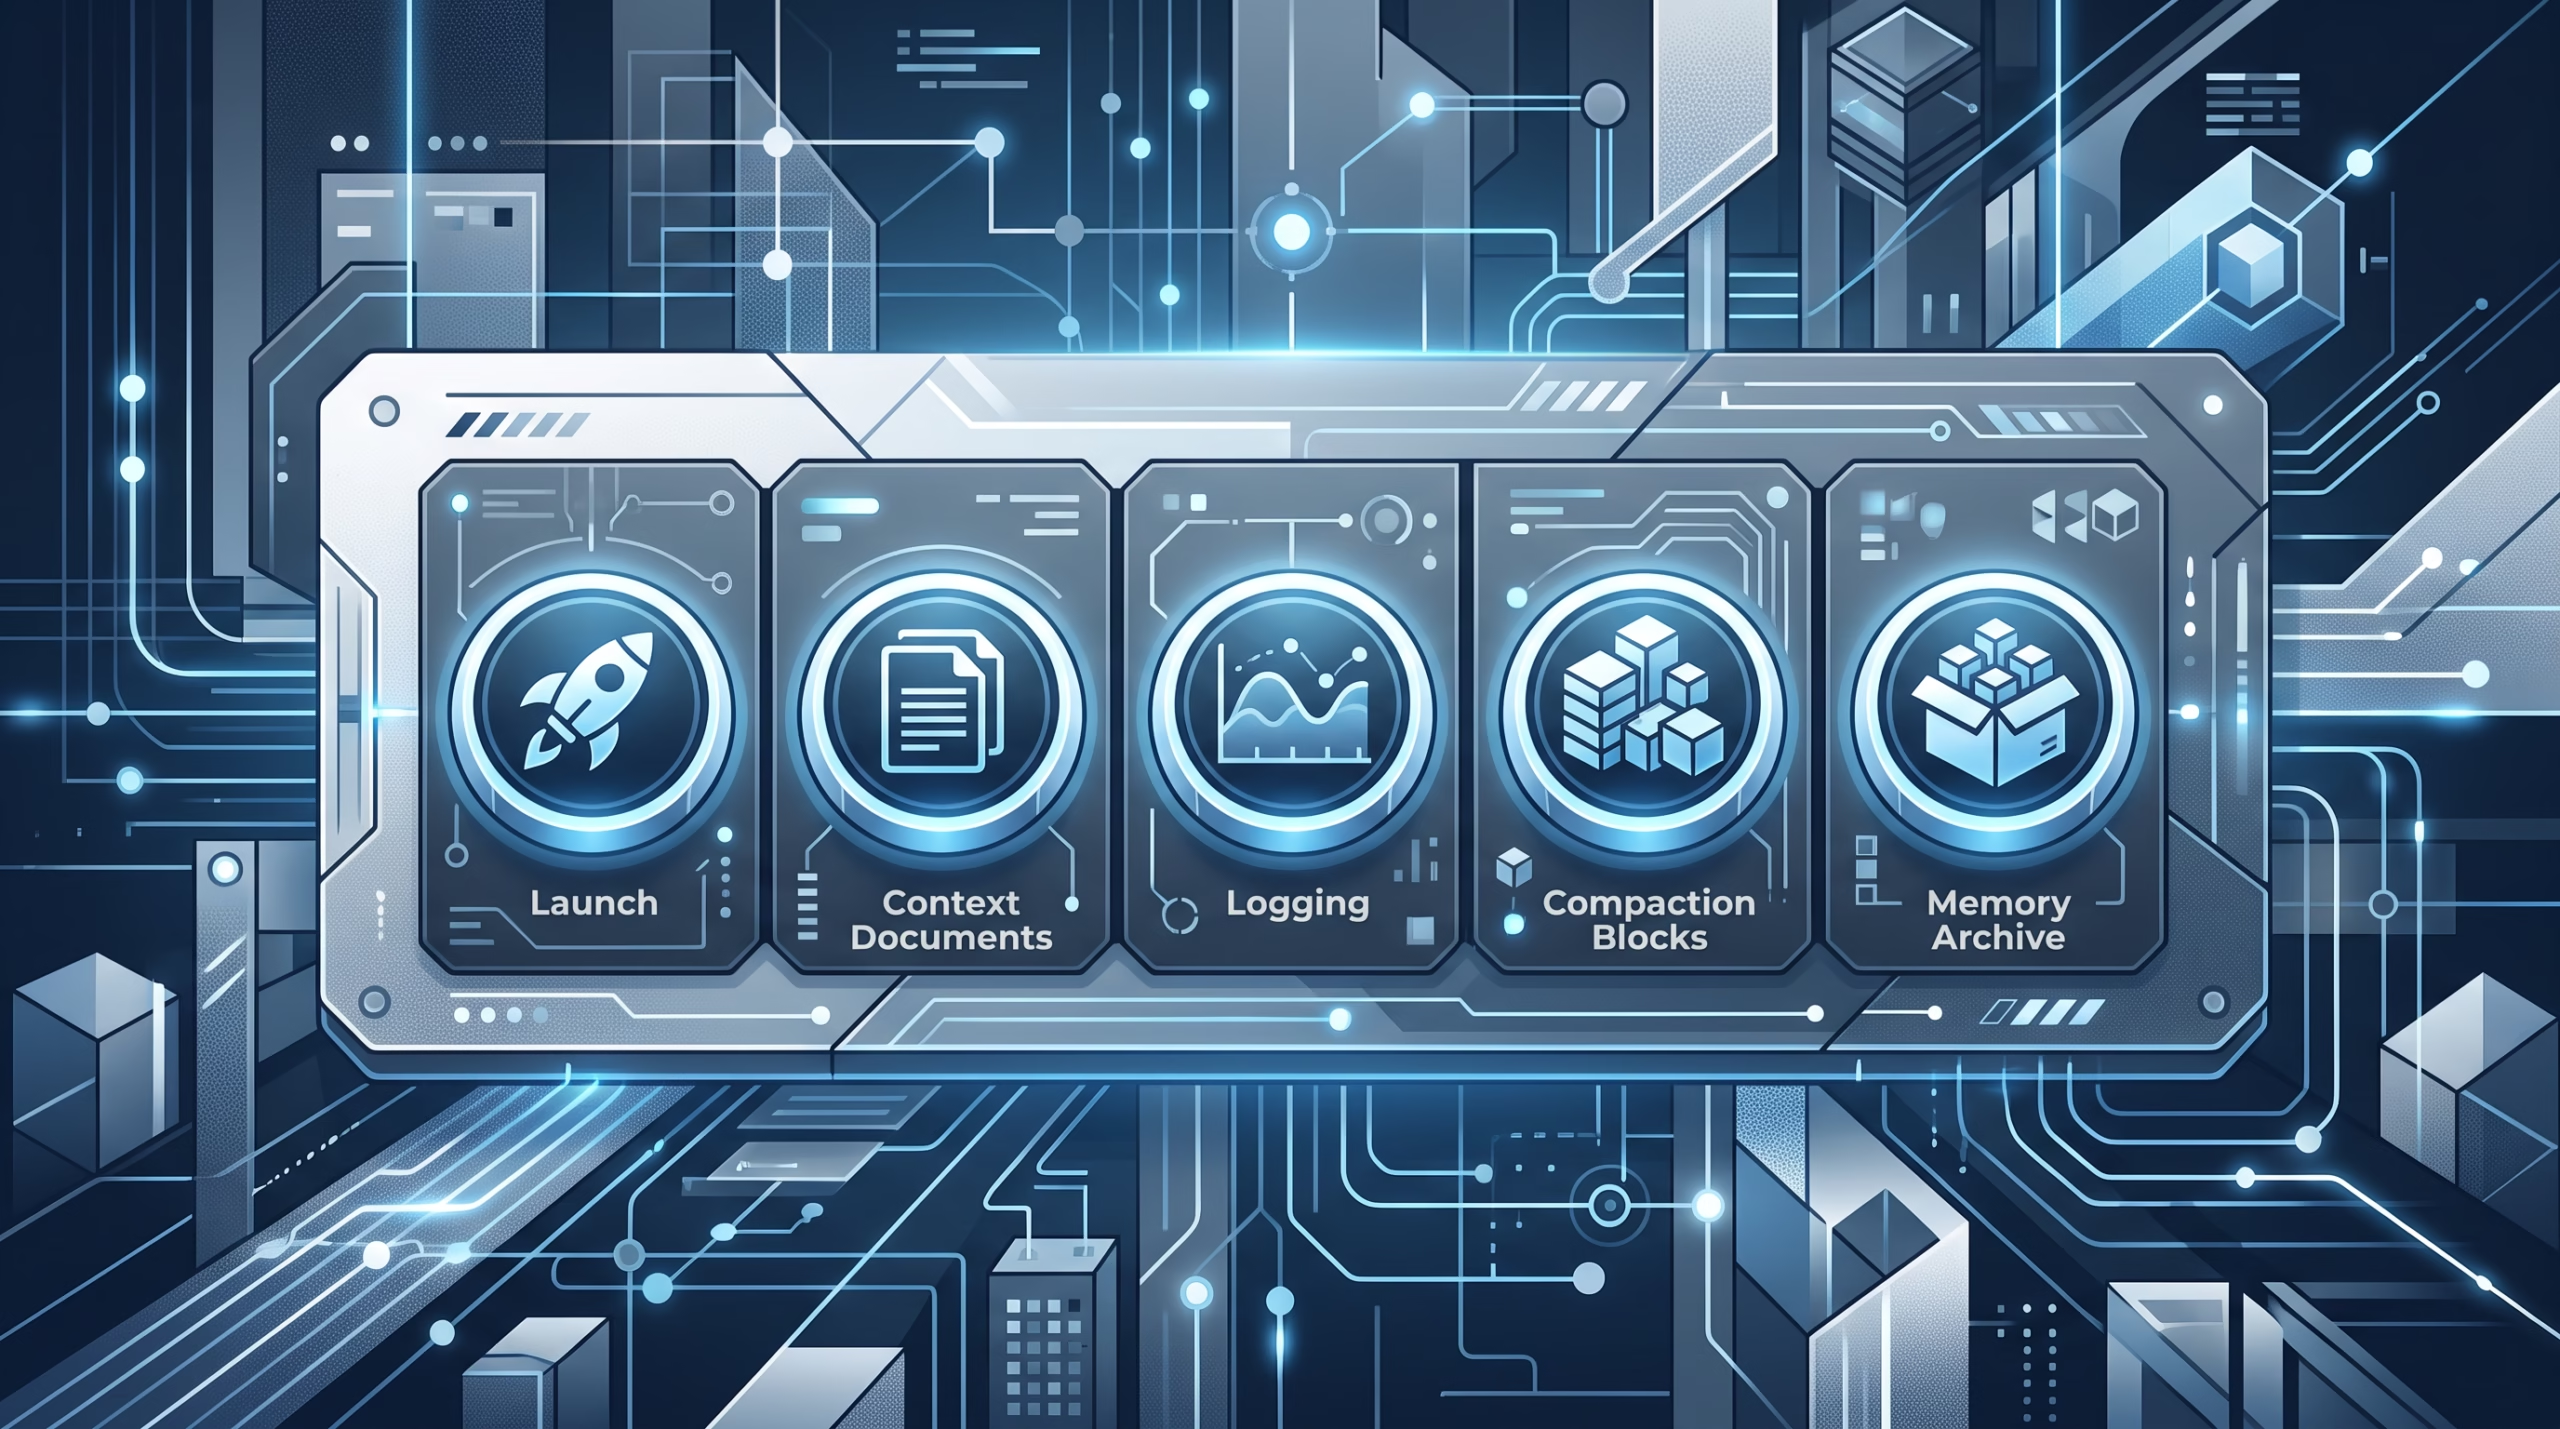
The current bundled catalog is small on purpose:
boot-mdruns workspace startup instructions fromBOOT.md.bootstrap-extra-filesadds selected workspace files to bootstrap context.command-loggerrecords command events to a JSONL log.compaction-notifieremits notices around supported compaction paths.session-memorysaves filtered recent conversation excerpts during resets and rollover.
That catalog tells you the most important thing about bundled hooks: they are not general-purpose automation. They are prebuilt answers to common operator needs around startup, context, logging, compaction, and memory.
OpenClaw’s parent hooks guide also draws an important boundary. Internal hooks are separate from plugin hooks, HTTP webhooks, and diagnostic events. If you want to modify prompts, intercept tools, or participate in plugin lifecycle contracts, bundled internal hooks are probably not the right surface. If you want another service to start work through HTTP, use webhooks instead. If you want telemetry, use diagnostic events.
The five bundled hooks, in plain English
The easiest mistake is to enable a hook because the name sounds useful. Start with what side effect you want, then pick the hook that owns it.
boot-md: startup instructions for the Gateway
boot-md listens to gateway:startup. When the Gateway starts, it looks for a nonempty BOOT.md in each configured agent’s resolved workspace and runs those instructions through an agent run.
The distinction matters. BOOT.md is not executed as a shell script. It is not injected as a normal bootstrap file. OpenClaw creates a fresh temporary session shaped like agent:<id>:boot:<run-id>, runs the instructions there, and cleans that session up after success or failure. Existing sessions and histories are preserved.
This is a good fit for short startup checks, housekeeping messages, or repeatable agent-side preparation. It is a poor fit for fragile one-time migrations. Startup can happen more than once, and the docs are blunt about it: keep boot instructions short and safe to repeat. Because the hook can trigger model calls and outbound effects, enabling it is a real operational decision, not a harmless toggle.
Verification is different from the other hooks. Because this is a startup-only event, enabling it does not replay the event. You verify it on the next Gateway start by checking the intended side effect and logs.
bootstrap-extra-files: controlled context injection
bootstrap-extra-files listens to agent:bootstrap. Its job is to add matching workspace bootstrap files to the model context before a run. That makes it useful when your workspace has package-level instructions or role files that should join the normal bootstrap set.
The config prefers paths. If paths is empty, the handler tries patterns, then files. Those are alternatives, not merged lists. Without patterns, the hook does nothing.
OpenClaw puts strict boundaries around what can be loaded. Paths resolve relative to the event workspace and must remain inside that workspace, even after symlink resolution. Only recognized basenames load: AGENTS.md, SOUL.md, IDENTITY.md, USER.md, BOOTSTRAP.md, and MEMORY.md. TOOLS.md is not a recognized runtime bootstrap basename.
The hook also inherits the normal bootstrap filtering and budgets. Reads are capped at 2 MiB per file. Injection defaults to 20,000 characters per file and 60,000 total, with a separate smaller cap for USER.md. That means “selected” does not always mean “fully injected.” The practical verification step is /context detail, because that shows what actually made it into the run.
command-logger: command audit breadcrumbs
command-logger listens to the command family. It appends one JSON line per emitted command event to <stateDir>/logs/commands.log. Each record includes timestamp, action, sessionKey, senderId, and source. Missing sender or source values become unknown.
This hook is the safest first test for many operators because it needs no model call and gives you a clear file to inspect. Enable it, send an authorized /new or /reset in a conversation you can safely reset, then check the log file on the Gateway host.
openclaw hooks enable command-logger
tail -n 5 ~/.openclaw/logs/commands.log
Do not overstate what it logs. Core emits /new, /reset, and /stop, not every slash command. It also does not rotate the log. Because it records session and sender identifiers, you should set file permissions and retention deliberately. OWASP’s logging guidance has the right mental model here: log enough “when, where, who and what” context to support operations and investigation, but avoid collecting more than you can protect.
compaction-notifier: visible compaction status when delivery supports it
compaction-notifier listens to session:compact:before and session:compact:after. It adds short notices before and after successful compaction on supported delivery paths. Those notices can include message counts and token counts when the data is available.
The important phrase is “supported delivery paths.” The notices travel through the compaction caller’s notice callback. If that callback is absent, enabling the hook does not guarantee a visible message. A before notice without an after notice can mean compaction was skipped, failed, or interrupted. Manual /compact is not a reliable way to test visibility because it does not supply the same hook-message delivery callback.
This hook is useful for user-facing clarity in long sessions, but it is not a compaction health monitor by itself. For actual compaction behavior, pair it with the compaction docs, Gateway logs, and /status.
session-memory: filtered excerpts at reset boundaries
session-memory listens to command:new, command:reset, and session:auto-reset. It saves recent user and assistant text when a session ends through /new, /reset, soft reset, or automatic daily/idle rollover.
By default, the artifact is written under the workspace as memory/YYYY-MM-DD-HHMM.md, with a numeric suffix when needed. Dates use the configured user timezone first, then process TZ, then the host timezone. The default entry count is 15 recent messages. Optional llmSlug can ask a model for a descriptive filename slug, but that adds a model call; leave it off if you do not want that extra call.
This hook is not a full transcript export. It writes a filtered excerpt. The docs say it omits slash-command text, tool messages, inter-session user input, silent reply markers, and duplicate delivery-mirror text. Manual resets do not await the file write or optional slug-model call. If you need to confirm it finished, wait for the “Session context saved to …” log line.
That limitation is fine if you use the hook for recall breadcrumbs. It is not fine if you treat the file as legal archive, analytics data, or complete conversation history.
Start with the side effect, not the hook name
A compact decision table helps:
| Need | Use this hook | Verify by checking |
|---|---|---|
| Run short repeatable startup instructions | boot-md |
Gateway restart logs and the requested side effect |
| Add approved workspace instruction files to context | bootstrap-extra-files |
/context detail |
| Record reset/new/stop command breadcrumbs | command-logger |
<stateDir>/logs/commands.log |
| Show supported compaction progress notices | compaction-notifier |
Visible notices plus Gateway logs or /status |
| Save recent conversation excerpts on reset or rollover | session-memory |
New Markdown file under memory/ and Gateway logs |
This is also the point where you should ask the awkward question: do you need a hook at all? If the task needs retries, durable state, long-running execution, or exactly-once semantics, a hook is probably the wrong surface. OpenClaw’s hook guide says handlers should stay short and bounded. It also says there is no general handler timeout, cancellation signal, durable event queue, automatic retry, or exactly-once guarantee.
How to enable and verify a bundled hook
The basic CLI path is simple:
openclaw hooks list
openclaw hooks info command-logger
openclaw hooks enable command-logger
With the default hybrid reload mode, config changes can apply without a restart. With reload mode off, restart the Gateway. If your config has multiple agents and no implicit owner, add --agent <id> when inspecting the relevant workspace.
The trap is assuming the report proves runtime execution. It does not. The OpenClaw docs separate three ideas:
- Requirements satisfied: the host has the needed OS, binaries, environment, and config.
- Enabled by config: the source and per-hook policy allow the hook.
- Loaded: the running Gateway selected and imported the handler.
The CLI fields ready, eligible, and loadable describe inventory and eligibility. They do not prove that the Gateway imported the handler, that the global selection includes it, or that the event fired. That is why every hook needs a side-effect check.
For command-logger, inspect the JSONL log. For bootstrap-extra-files, inspect context. For session-memory, inspect the workspace memory directory and logs. For boot-md, restart and check the requested startup outcome. For compaction-notifier, test on a delivery path that can show notices, then confirm compaction separately.
Security and privacy checks before enabling hooks
Internal hooks are trusted code. They run with the Gateway process’s filesystem, network, and environment access. That warning appears in the main OpenClaw hooks guide for a reason. Even bundled hooks are maintained by OpenClaw, but their side effects can still create data you need to govern.
For command-logger, decide who can read commands.log, how long it should live, and whether your backup system will copy it elsewhere. It records session keys and sender identifiers. That is operationally useful and privacy-relevant.
For session-memory, decide whether filtered excerpts are acceptable for the workspace. They may include recent human and assistant text. They are not raw tool output, but they are still conversation data. If session transcript indexing is also enabled, one conversation can be represented in both memory files and transcript search. That may be exactly what you want, or it may create noisy overlapping recall.
For bootstrap-extra-files, keep the path list tight. The hook already limits basenames and workspace boundaries, but you still choose what files are eligible. Do not use it as a lazy way to stuff whole repos into context. Context budgets are finite, and noisy bootstrap makes agents worse.
For boot-md, write instructions that are safe on every restart. Avoid anything that should happen only once unless it is idempotent and checks its own prior state. Startup hooks are powerful because they can use model and tool capabilities. That is also why they deserve review.
How bundled hooks compare to other hook systems
OpenClaw is not alone in using events as automation boundaries. GitHub Actions has workflow triggers that run when repository events, schedules, or outside events occur, and many triggers have activity types to narrow what fires. Claude Code documents hooks around session, turn, and tool-use lifecycle points.
The useful comparison is not that these systems are identical. They are not. The useful comparison is that mature automation surfaces make event timing explicit. A hook name is a contract about when context is available, whether work is awaited, and what the handler can safely affect.
OpenClaw’s event types make that contract visible. Some events, such as command:new and agent:bootstrap, are awaited. Message observation events are asynchronous and are not a complete transport audit. message:sent can report a failure for a path that emitted an outcome, but absence of an event is not proof of success or failure. That nuance matters when you are building operator expectations around hooks.
When bundled hooks are the wrong tool
Use bundled hooks for short side effects tied to OpenClaw lifecycle events. Reach for something else when the work needs more operational weight.
Do not use a bundled hook as a durable job runner. If the handler starts heavy background work and does not await it, that work escapes the handler’s error boundary and can outlive the session or process that made the event meaningful. If the work must survive restarts, needs retries, or needs a visible run record, use an automation or service that owns that lifecycle.
Do not use command-logger as a full audit log. It records emitted command events, not every user action. Use it as a command breadcrumb, then design real observability around the events you actually need.
Do not use session-memory as a transcript archive. It is a filtered excerpt. If you need full transcript review, use transcript-aware tools and retention policies.
Do not use bootstrap-extra-files to patch weak workspace instructions. Fix the canonical files first. Extra bootstrap files are best when the workspace has legitimate subproject context, not when the root instructions are unclear.
A safe rollout pattern
For a production Gateway, roll bundled hooks out one at a time:
- Pick the exact side effect you want.
- Read
openclaw hooks info <name>. - Enable the hook locally on the Gateway host.
- Trigger the smallest safe event that should fire it.
- Verify the real side effect.
- Set retention, permissions, and owner notes for any generated files.
That may sound slow, but it prevents the common failure mode: a hook looks eligible in CLI output, but nobody has proven that the running Gateway imported it or that the intended event path actually fires in the channel you care about.
If you are enabling your first bundled hook, start with command-logger. It is easy to test, easy to disable, and it teaches the right habit: hook config is only half the story; evidence is the other half.
FAQ
Are OpenClaw bundled hooks sandboxed?
No. Internal hooks run as trusted Gateway-process code. Review what a hook does before enabling it, especially for non-bundled hooks from workspaces, packages, or downloaded sources.
Do I need to restart the Gateway after enabling a bundled hook?
It depends on reload mode and the hook. In the default hybrid reload mode, config changes can apply without a restart. With reload mode off, restart manually. Startup-only behavior such as boot-md waits for the next Gateway start because enabling it does not replay gateway:startup.
Does openclaw hooks list prove the hook is running?
No. The report shows inventory and eligibility. It does not prove that the running Gateway selected, imported, and executed the handler. Always verify the hook’s side effect.
Can session-memory replace normal memory work?
No. It saves a filtered excerpt at reset and rollover boundaries. It is useful for recall breadcrumbs, but durable memory still needs curation. Important facts and decisions should still land in the right memory files.
Which bundled hook should I enable first?
For most operators, command-logger is the cleanest first hook. It needs no model call, creates an inspectable JSONL file, and gives you a low-risk way to learn the enable-and-verify loop.
Bottom line
OpenClaw bundled hooks are small, practical controls for common Gateway automation. They are strongest when you treat them as event-bound side effects with evidence: a log line, a context detail view, a memory artifact, or a visible notice. They are weakest when you treat them as a hidden workflow engine.
Review your current hook config, enable one hook that solves a real operator problem, and verify the outcome on the Gateway host. That discipline is what keeps built-in automation boring in the best possible way.